Formal Methods
Proving a Network Action Is Safe Before It Runs
The usual runbook check approved 98% of unsafe maintenance actions. Exact graph methods made zero errors, and the fastest checks a 14,680-device network in 0.19 s.
Raghav Balasubramaniam
Result in one line. Across 2,000 random maintenance scenarios, the usual runbook check approved 98% of the unsafe actions, including 156 of the 168 actions that would have cut servers off entirely. Two exact methods (max-flow and block-cut trees) made zero errors. The block-cut method checked a 14,680-device network in 0.19 seconds; max-flow took 218 seconds on 3,672 devices.
Any system that proposes remediation actions, whether a person, a script or a model, will sometimes propose a bad one. The standard defence is a runbook check: "will this reboot disconnect anything?"
This note shows that the check misses almost all unsafe actions in realistic conditions, because it ignores two things: other work already in progress, and the loss of backup paths. It then shows that an exact check, one that proves the action is safe rather than testing a few cases, can run in under 0.2 seconds on a network of 15,000 devices, using graph algorithms from the 1970s.
The problem
An action here is a contract: "take these devices out of service" (reboot, drain, upgrade, replace optics). The question is whether the network still meets its promises afterwards. Three things make this harder than it looks:
Other work in progress. Rebooting aggregation switch A is fine. Rebooting it while a colleague is upgrading its twin B cuts the pod off. Each action is safe alone and unsafe together.
Devices already down. A failure elsewhere may already have used up the redundancy.
Losing backups is not the same as losing service. After an action every server may still be reachable, but some may now hang on a single path. For critical customers that is itself a violation, since the next failure takes them down.
The rule we verify
For every server, count its resilience: the number of paths to the core that share no device, capped at 2. Resilience 2 means it survives any one more failure. Each server has a required level R: normal pods, R = 1 (must stay reachable); critical pods, R = 2 (must keep a spare path; these pods have 3 aggregation switches, so single-switch maintenance is still allowed).
An action is safe if, for every server, resilience after ≥ min(resilience before, R). "After" includes devices already down, all in-flight actions, and the proposed action. This is a "do no harm" rule: if a server is already degraded, the action must not make it worse.
Five ways to check
Method | What it checks | Exact? |
|---|---|---|
Runbook | Does this action alone disconnect any server right now? | No |
State-aware reachability | Same, but counting devices already down and in-flight work | No (ignores backup paths) |
Brute force (oracle) | Remove each device in turn and search the graph each time | Yes, O(V·(V+E)) |
Max-flow | Menger's theorem: device-disjoint paths = max-flow; one flow per server | Yes |
Block-cut tree | Biconnected components, computed once for the whole network | Yes, O(V+E) |
Why the block-cut method works
Add one virtual node joined to every live core router. A server has two device-disjoint paths to the core exactly when it and the virtual node sit in the same biconnected component: a piece of the graph with no single point of failure. The components of the whole graph come from one depth-first search (Hopcroft and Tarjan, 1973). So one linear-time pass gives the resilience of every server at once, instead of one flow calculation per server. It is exact for resilience up to 2. Stricter rules (3+ disjoint paths) need max-flow.
These are proofs, not tests. The answer covers every possible single failure after the action, not a sample.
Experiment 1: how often do today's checks get it wrong?
Network: 6 pods of a 3-tier Clos design (2 cores, dual-homed aggregation and access, dual-homed servers). Two of the pods are critical, with 3 aggregation switches each. We generated 2,000 random scenarios, each with 0–2 devices already down, 0–2 actions in flight, and a proposed action on 1–2 devices (core 15%, aggregation 45%, access 40%). The brute-force oracle gives the true answer.
744 of the 2,000 actions were unsafe. 101 of those were safe on their own and unsafe only because of the network's current state or other work.
Check | Unsafe actions approved | Safe actions blocked |
|---|---|---|
Runbook (action alone) | 98.4% | 0% |
State-aware reachability | 77.4% | 0% |
Max-flow | 0% | 0% |
Block-cut tree | 0% | 0% |
Which kind of harm each check misses
Split by the kind of harm, the two approximate checks fail in different places. Only the exact methods catch both.
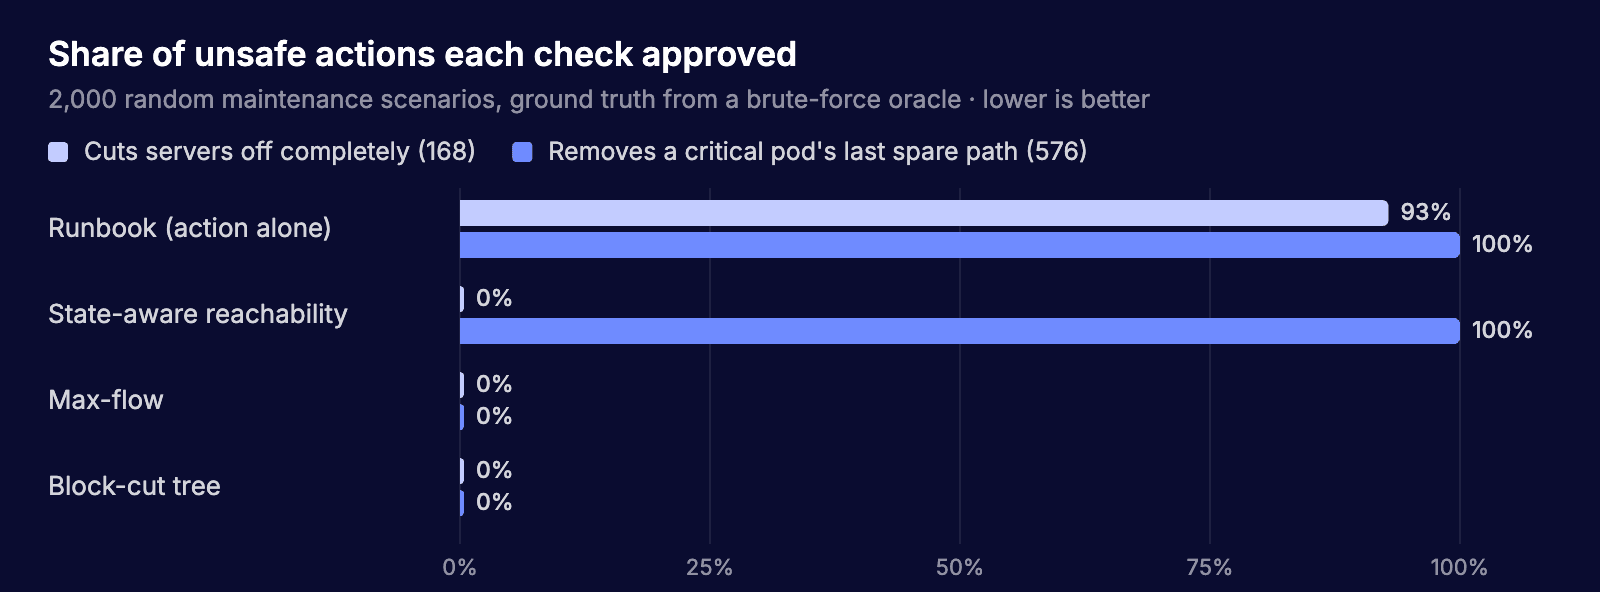
Figure 1. Share of unsafe actions approved, split by kind of harm. Only the exact methods catch both.
Kind of unsafe action | Count | Runbook approved | State-aware approved | Exact methods approved |
|---|---|---|---|---|
Cuts servers off completely | 168 | 156 | 0 | 0 |
Removes a critical pod's last spare path | 576 | 576 | 576 | 0 |
Ignoring the current state is the dangerous gap. The runbook check approved 156 of the 168 actions that would disconnect servers outright. It looks at the action alone, so it cannot see that the twin switch is already down or being worked on.
Counting the current state fixes outages but not risk. The state-aware check caught every disconnection, but none of the 576 actions that quietly left critical customers one failure away from an outage.
Only a resilience-aware check catches both, and here both exact methods agreed with the oracle on every scenario. The exact rates depend on our scenario mix; the ranking is what matters.
Experiment 2: is it fast enough for a live NOC?
Time for one full safety check (before and after, all servers), averaged over 3 random scenarios per size, on one laptop CPU core in plain Python (networkx).
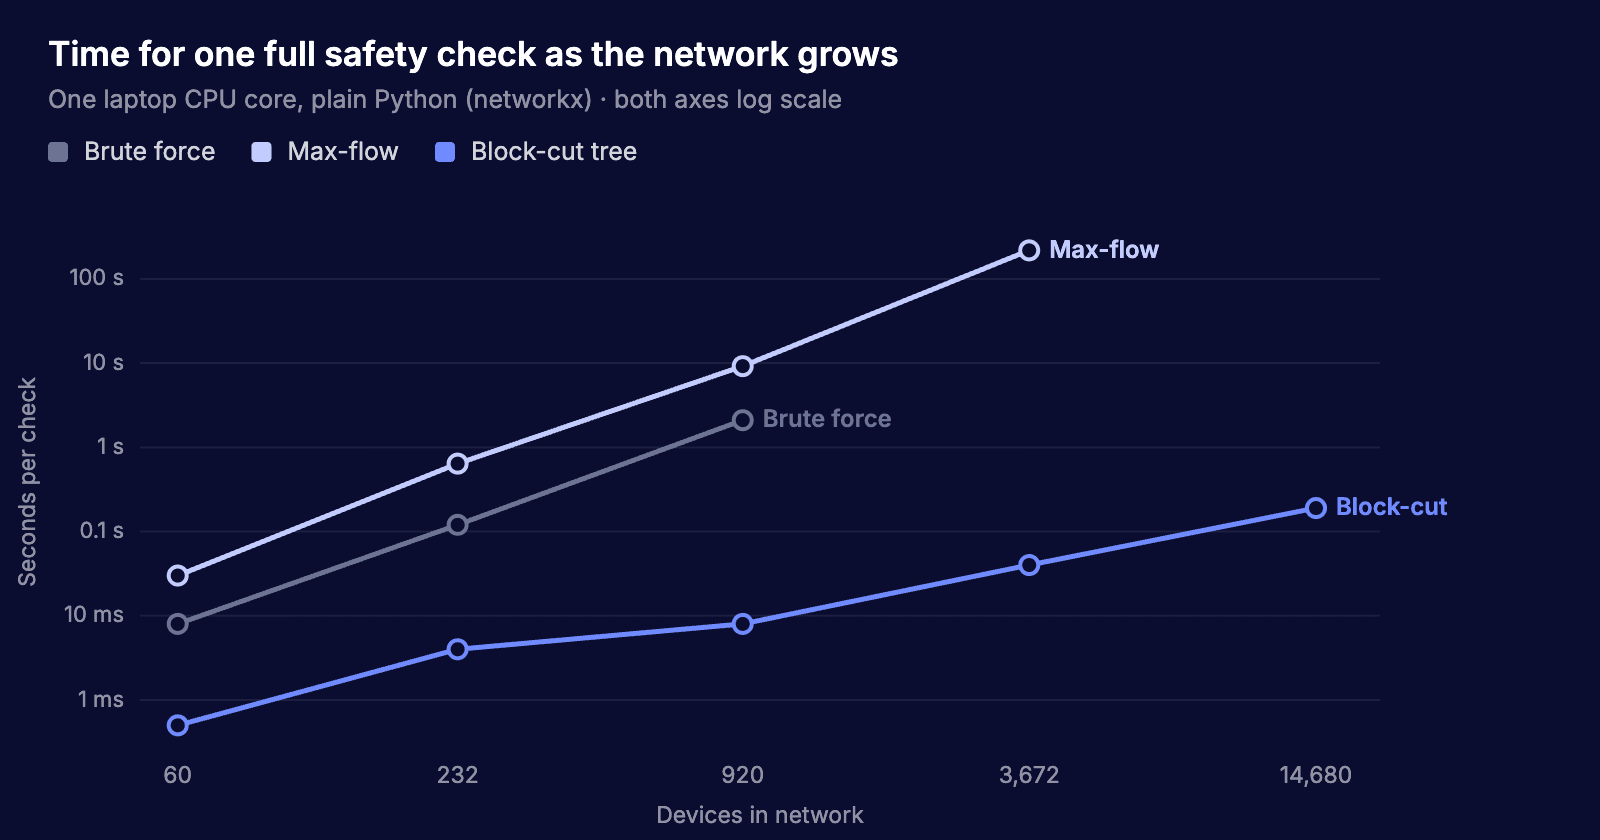
Figure 2. Time for one full safety check vs network size, log-log. Block-cut stays under 0.2 s at 14,680 devices.
Pods | Devices | Links | Brute force | Max-flow | Block-cut tree |
|---|---|---|---|---|---|
4 | 60 | 124 | 0.008 s | 0.03 s | 0.0005 s |
16 | 232 | 484 | 0.12 s | 0.64 s | 0.004 s |
64 | 920 | 1,924 | 2.1 s | 9.2 s | 0.008 s |
256 | 3,672 | 7,684 | not run | 218 s | 0.04 s |
1,024 | 14,680 | 30,724 | not run | not run | 0.19 s |
Block-cut grows almost in step with network size. 0.19 s for ~15,000 devices is fast enough to re-check every proposed action, and to re-check every in-flight action whenever the network changes.
Max-flow grows much faster. 218 s at 3,672 devices is too slow for live use in this form. Two fixes we have not tried: only re-check servers in pods the action touches, and use a compiled flow library instead of pure Python.
Brute force is only useful as a ground-truth oracle in tests.
What it means
A verification step between "the system proposes an action" and "the action runs" is cheap and catches real problems. This is the core of what we call adaptive formal verification: re-check against the live state and other in-flight work, not a static runbook.
The mathematical guarantee comes from classical graph theory (Menger, 1927; Hopcroft and Tarjan, 1973). The proposer can be anything, including a probabilistic model, because the check does not trust it.
When the check blocks an action, it can say exactly why: "server p3-srv-1-2 would drop from 2 paths to 1; required 2 for this tenant". That gives the audit trail regulated operators need.
Limits
Connectivity only. We verify that paths exist between devices. We do not check routing policy, ACLs, VLANs, capacity, or whether traffic actually uses the backup path. Those need a model of the configuration, typically with an SMT solver (a program that proves or disproves logical rules).
Devices fail, not links. Link-level resilience uses the same methods with edge cuts instead of vertex cuts. Not implemented here.
Synthetic topology and scenarios. A regular Clos design. Real telco networks with rings and irregular meshes should be tested next; the algorithms do not depend on the shape.
Resilience capped at 2. Enough for "survive one more failure". Stricter rules need max-flow and the speed-ups above.
Next steps
Run on a real customer topology export (CMDB or discovery data).
Add capacity: does the remaining path have enough bandwidth to carry the moved traffic?
Add routing-policy checks for the actions where connectivity is not enough.
Make max-flow local to the affected pods and measure again at 15,000 devices.
References
K. Menger, Zur allgemeinen Kurventheorie, Fundamenta Mathematicae, 1927.
J. Hopcroft and R. Tarjan, Algorithm 447: efficient algorithms for graph manipulation, Communications of the ACM, 1973.